Intro
2026 / Summer
Do AI models rate faces like humans?
AI models do not judge facial attractiveness like humans; they rate almost everyone above average and never give the lowest scores. However, models can rank faces similarly to how people do.
Every face is drawn from the Face Research Lab London Set: 102 neutral, front-facing portraits normalized for pose, lighting, and framing. 2,513 people rated each on a 1–7 attractiveness scale.
Four commercial models (Claude, ChatGPT, Gemini, and Grok) rated the same faces one at a time, with no memory of the faces they had already seen. Each model rated every face repeatedly, and we averaged those into a single stable score.
- Faces rated
- 102
- Human raters
- 2,513
- Frontier models
- 4
- Rating scale
- 1 - 7
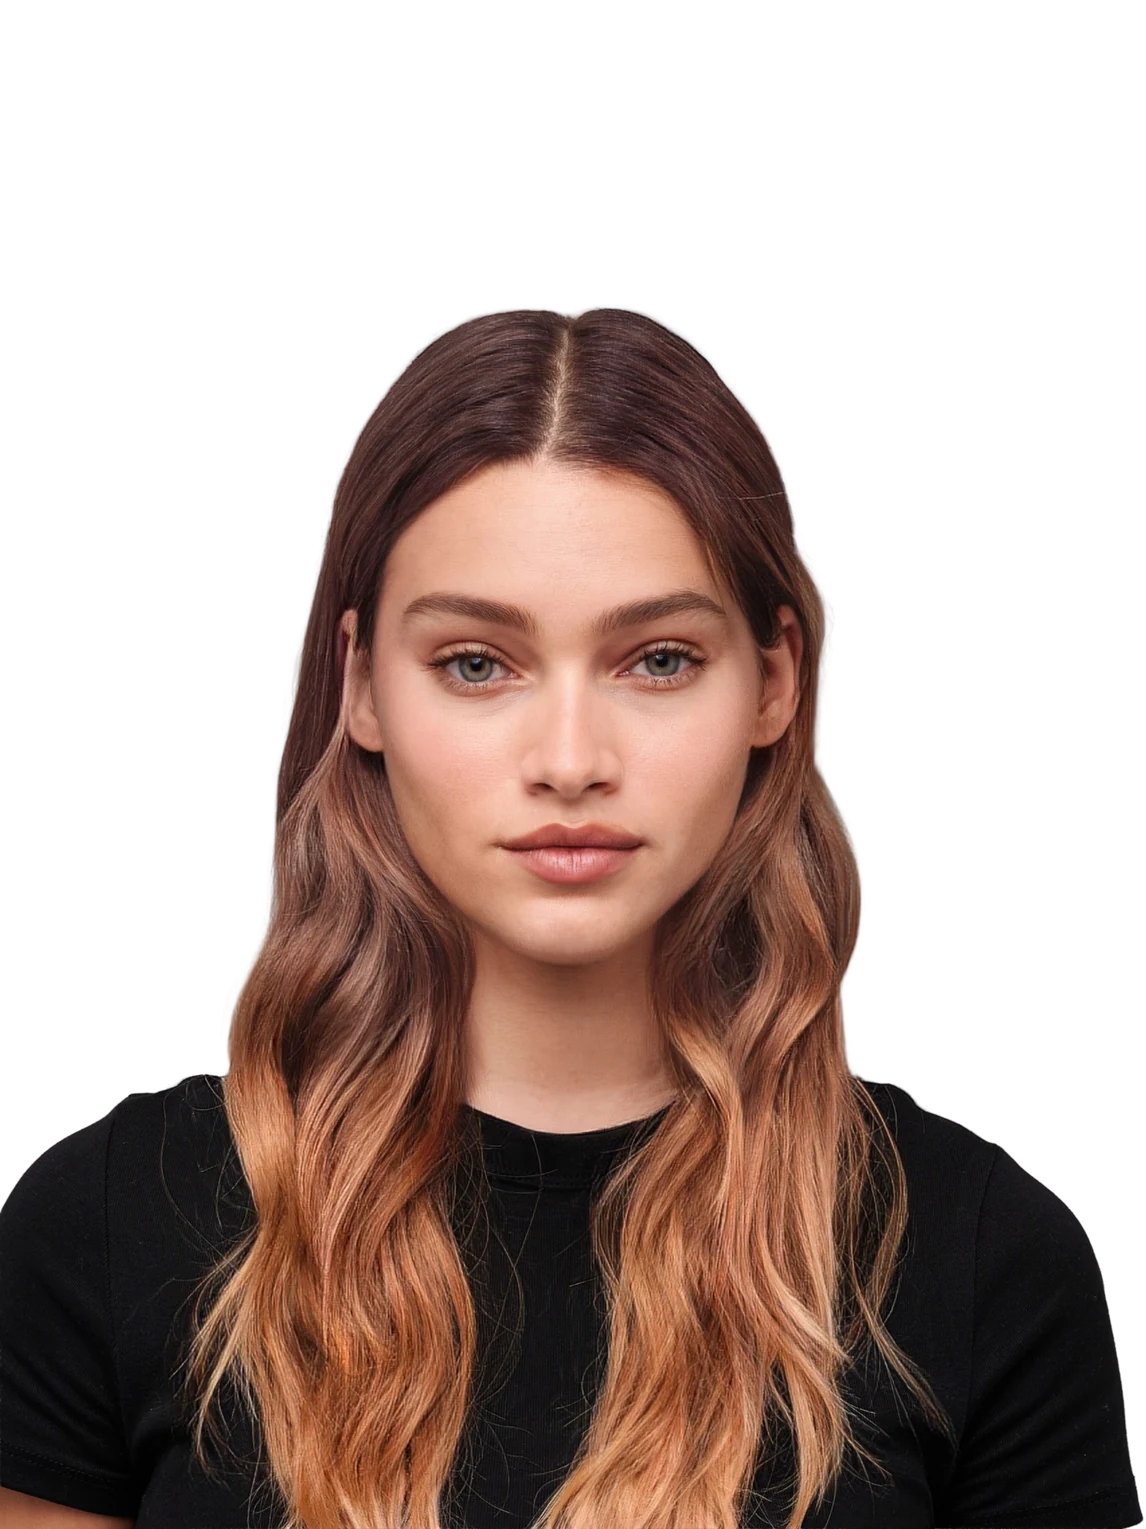
Human said
5.9 / 7
7th / of 102
AI said
6.7 / 7
6th / of 102
AI model
- Claude
- 6.4
- ChatGPT
- 6.6
- Gemini
- 6.8
- Grok
- 7.0
- On the ranking
- 1 place apartClose
- On the number
- + 0.8 pointsInflated
This face was not part of the study set, and the numbers are only indicative of the pattern we found. All real results are found below.
Beauty is no quality in things themselves: it exists merely in the mind which contemplates them; and each mind perceives a different beauty
AI-human agreement
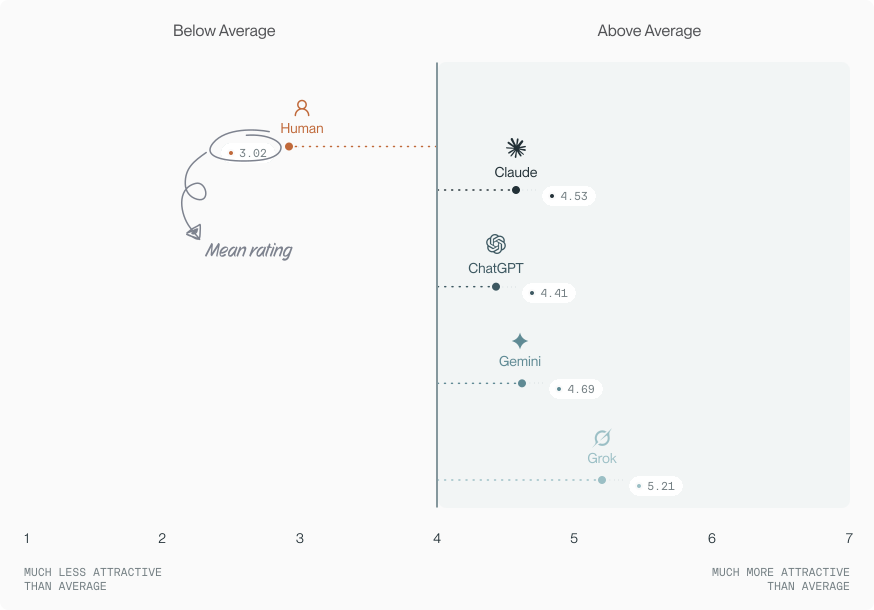
Humans use the full rating scale. AI compresses ratings towards the middle.
The bar chart below shows that humans rated faces using the full scale, whereas AI did not. No AI model rated anyone a 1 out of 7, and only Grok gave the highest rating.

Humans
mean 3.02

ChatGPT
mean 4.41

Claude
mean 4.53

Gemini
mean 4.69

Grok
mean 5.21
Human-AI agreement
Humans and AI mostly agree in their attractiveness rankings
Each dot is one of the 102 faces in the study. The diagonal line represents the model and the average human giving the exact same rating. A dot above the line indicates that the model rated that face more favorably than humans did; a dot below indicates the opposite.
Claude rating
ρ = .76 [.67, .83]
Average human ratingSpearman ρ = .76 [.67, .83]
Rank agreements between .58 and .76 are not trivial. All models, except Grok, order the faces in terms of attractiveness close to how humans do. It is also evident that the models gave a higher rating to almost every face, with only a couple of faces being rated higher by humans.
The line representing the pattern followed by the dots is more horizontal than the diagonal line in all the graphs, indicating that there is less agreement for faces with lower ratings according to humans than for faces with higher ratings. The lines get closer and closer to the diagonal line as the average human rating increases.
how we asked
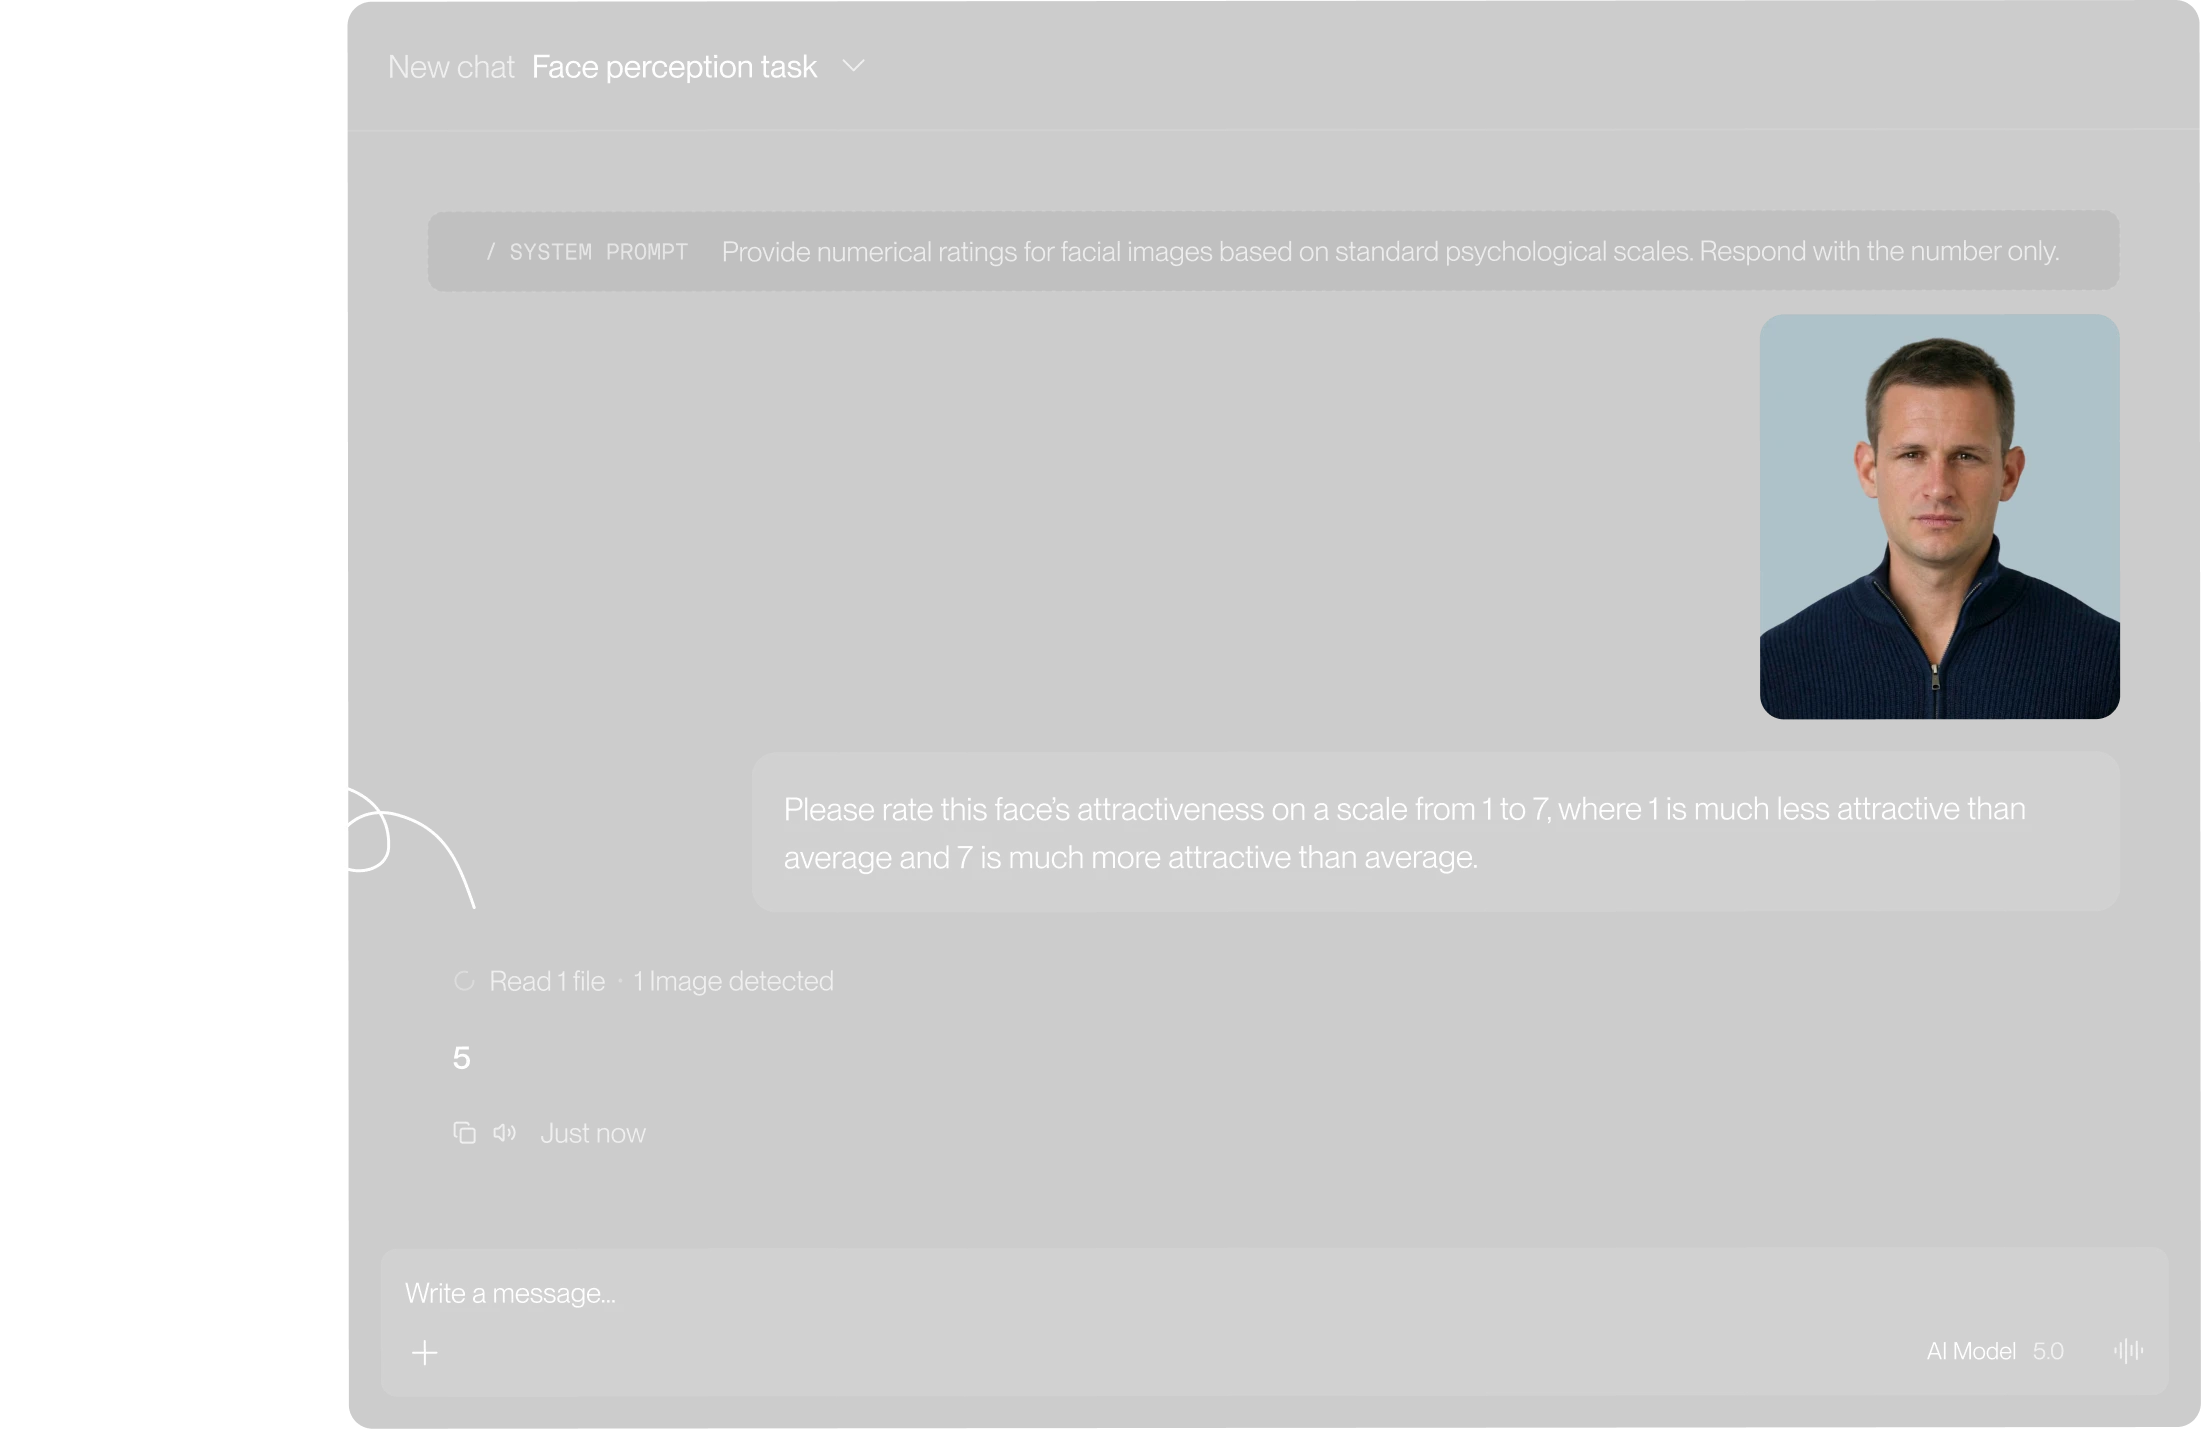
Asking AI to rate faces.
At scale, we used programmatic API calls, equivalent to the exchange shown below.
Facial characteristics
Humans judge women as more attractive than men, AI less so
Human participants rate women’s faces about 0.65 points higher on average compared to men’s faces. In AI models this gap shrinks to only 0.1–0.2 points.
Face gender
The female premium
Humans
Claude
ChatGPT
Gemini
Grok
Facial characteristics
AI models reflect the human age bias: AI and humans judge older faces as less attractive.
Humans and AI models alike judge the age of a face similarly; predicted attractiveness ratings drop across every type of rater.
Face age
The one thing everyone agrees on
Predicted rating falls with each additional year of face age for humans and all four models alike. The slopes run nearly parallel.
Predicted rating
- Grok-0.24 / decade
- ChatGPT-0.33 / decade
- Gemini-0.46 / decade
- Claude-0.49 / decade
- Humans-0.38 / decade
Rater characteristics
The models agree slightly more with women’s judgments.
We looked into whether AI models behaved like a specific human demographic, but the differences were minimal. However, a formal test showed that AI judgments were less aligned with male ratings than with female raters. We considered more specific rater profiles, and found that AI models agree most strongly with women under 30 who reported attraction to women. The lowest agreement occurred with men aged 23–30 attracted to men.
AI-pooled agreement by rater profile
Spearman ρ · sex / age / attracted-to · axis starts at .30
Rank agreement by rater sex
Claude
GPT
Gemini
Grok
- Female
- Male
Male raters track the models less closely
Claude
GPT
Gemini
Grok
AI Pooled
Interaction β (all p < .05)
Female
* Refers to the gender participants reported attraction to
Male
* Refers to the gender participants reported attraction to
AI-to-AI agreement
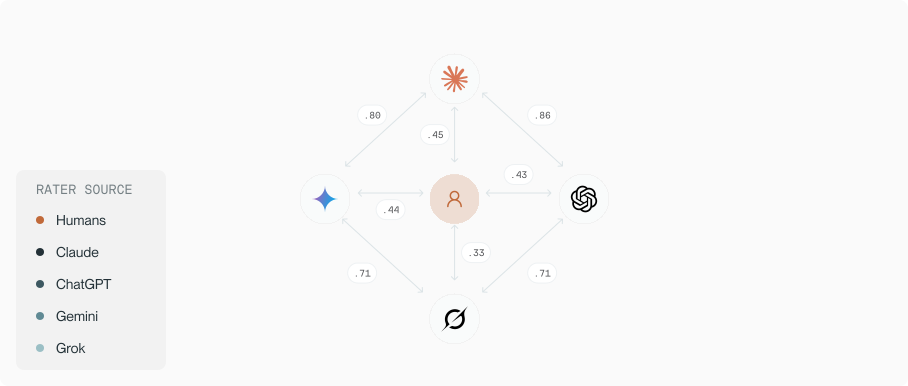
AI models strongly agree with each other except for Grok.
AI models agree more strongly with each other than with the average human. Claude, ChatGPT, and Gemini behave very similarly whereas Grok is the outlier (but still shows strong rank agreement).
Read study
Want to read the full study?
Everything on this page comes from a preprint study. The complete paper includes an introduction to the research topic, the complete methodology, extended results, and the interpretation of our findings.
QOVES Lab